Nouman Ahmad
open to remote roles

Nouman
Ahmad

AI Engineer — agentic RAG · multi-agent · production backends

I build production agentic RAG and multi-agent systems.

queryanswersupervisorkb · legalkb · financekb · hrkb · support
supervisor → specialists → answer
Built

What I build.

Multi-agent orchestration

supervisor → specialistsparallelretriesaudit
built at Levitate Data

Multi-tenant platform

Cognito authRBACscoped API keysrate limitsusage billing via outbox
built at Levitate Data · WebifyAI

Ingestion pipelines

PDF · DOCX · OCRweb · YouTubeaudio · video→ Qdrant
built at WebifyAI
Experience

Where I built it.

  1. Levitate Data

    Machine Learning EngineerAug 2026 – now
    multi-agent orchestrationLLM-as-judge evalsCognito auth & RBACusage billing (outbox)
  2. WebifyAI

    AI/ML EngineerMay 2024 – Aug 2026
    multi-tenant RAG platformdoc/audio/video ingestionCelery workersAWS ECS · CDKElectron desktop AI app
  3. Netsol Technologies

    AI/ML Engineer InternJan – Mar 2025
    LLM CV extractionGeminiStreamlit
Case studies

Built, measured, improved.

From a B2B enterprise RAG platform. Each change was tested against a bar set in advance.

01

Single vs multi-agent

Should agent teams be the default?

Not made the default.

A standard boss lost. Teams won only with a strong boss rewriting answers, or an ask-every-department rule.

0tests run
team wontiesingle won
02

Parallel delegation

Specialists run at the same time, not one after another.

~0%faster end to end
sequential1.0×parallel~0.67×time saved
03

Routing rule

One explicit rule for ambiguous questions.

~+0pts fact recall
ambiguous questionsbeforeafter · +5final run0 failures / ~112
04

Cost vs quality

Cheaper model tiers: worth the switch?

35–60%lower cost per answer
−0pts fact recall
✕ held · not shipped
cost per answer →fact recall ↑recall barcurrent tier−35% cost−60% cost−5 pts recallHELD
How I evaluate

Decide the bar first. Then run.

01

Hypothesis

One claim, one metric.

02

Pass criteria

Written down before the run.

03

LLM-as-judge

Rubric-based grading.

04

Bootstrap CIs

95% interval on the difference.

05

Ship / don't ship

Clears the bar → ship.

✓ ship✕ hold
Projects

Things I built on my own time.

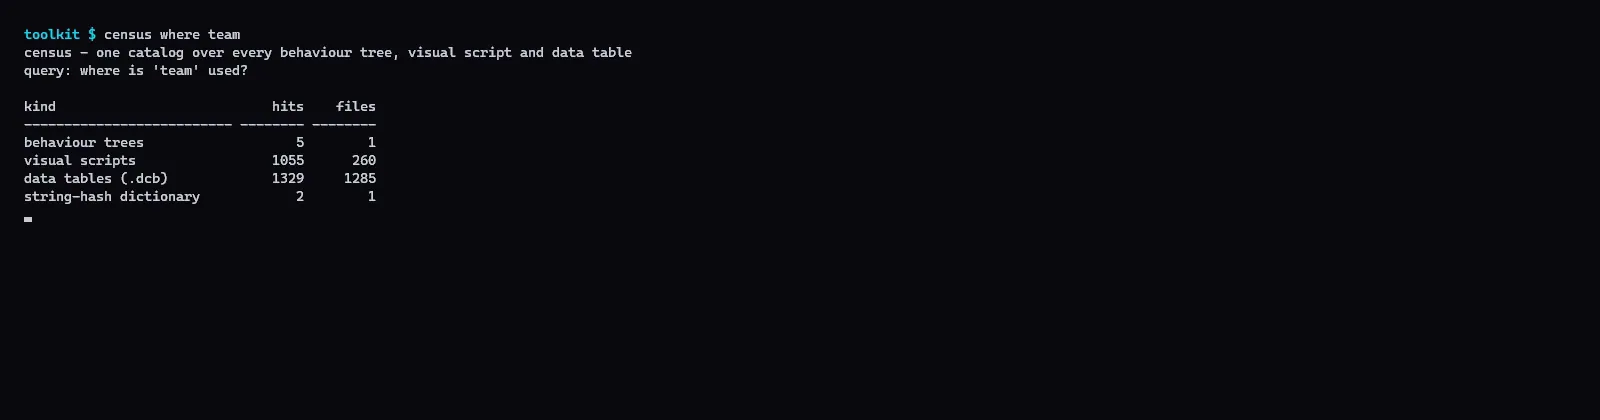
Terminal: one command searches thousands of game files in seconds

Game RE Toolkit

An agentic Claude Code workflow for reverse engineering game files: scripted tools, review gates, state notes.

Claude Codemulti-agentPythonreverse engineering
private code

LogsMate

Local LLM log analysis: RAG over raw logs turns them into structured incident summaries, fully offline.

RAGBM25rerankingChromaDBOllama · Llama 3.2
private code

AliceSpeaks

Local-first desktop voice assistant: realtime speech, local LLMs, human-confirmed actions. In progress.
PySide6Whisperlocal LLMsTTS
private code
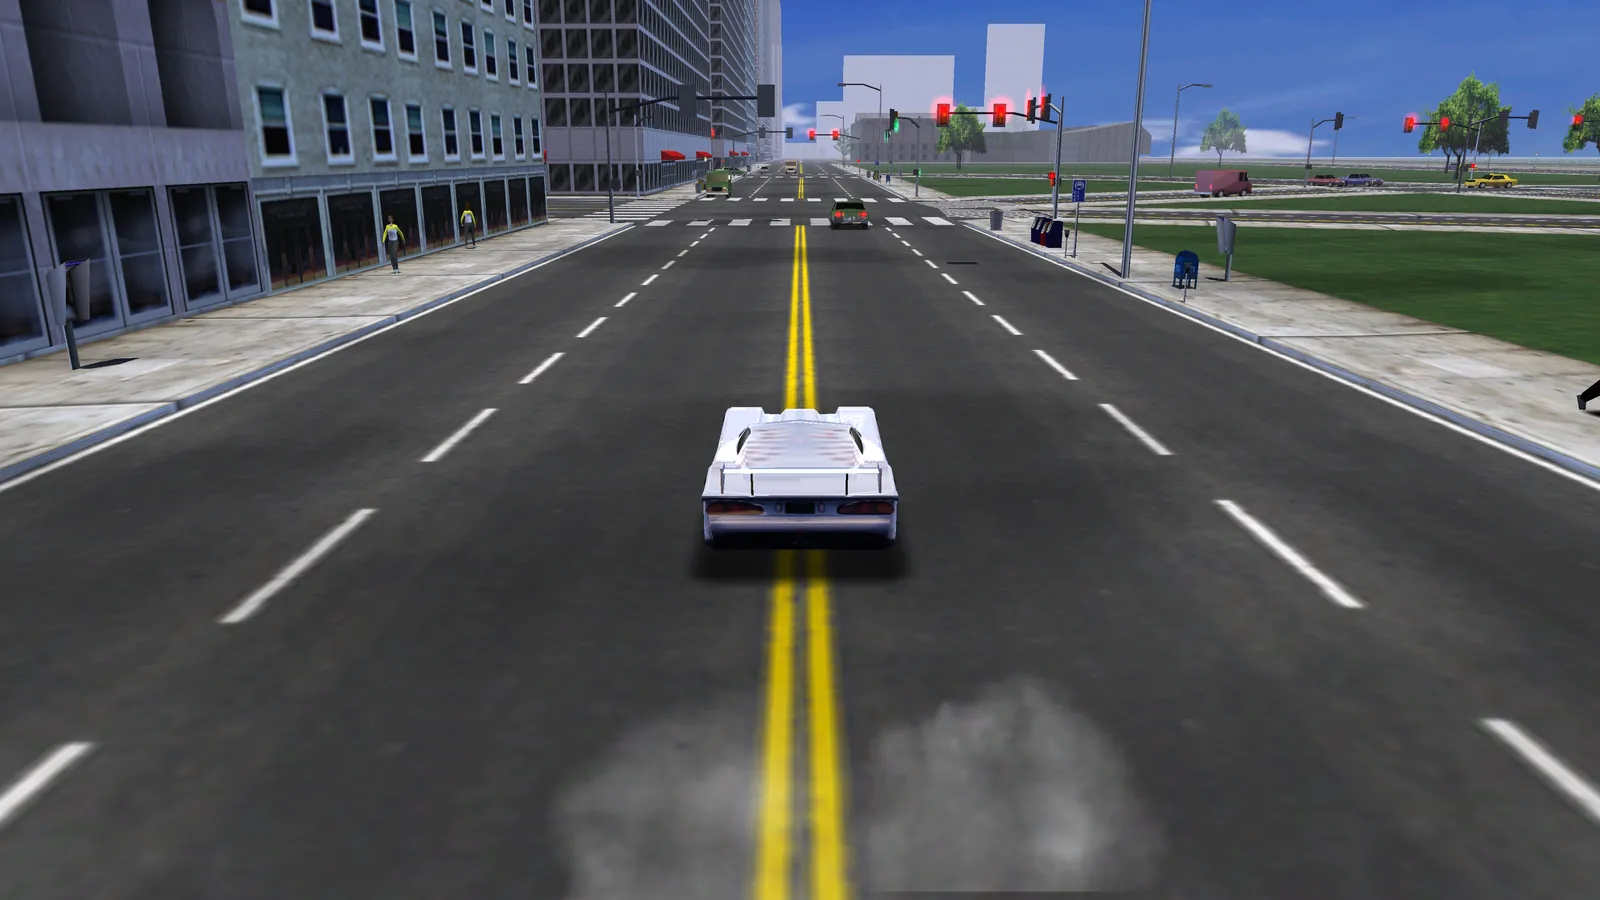
Before: Day street: original renderer vs upgraded lighting and shadows
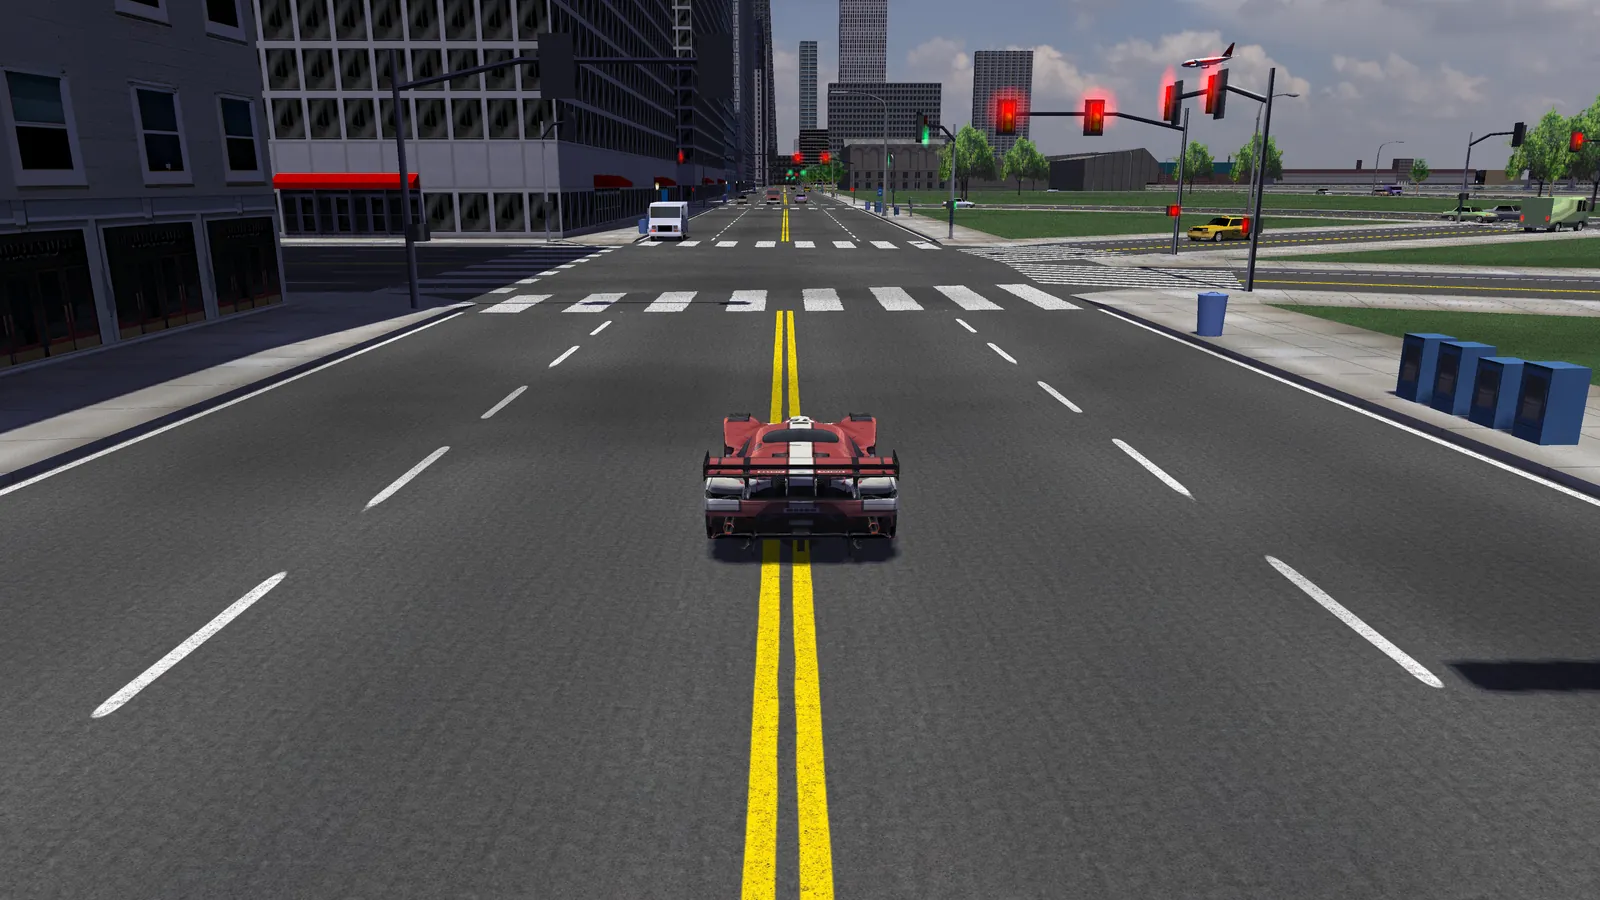
After: Day street: original renderer vs upgraded lighting and shadows
BeforeAfterDay

Legacy Engine Graphics Upgrade

Modern rendering for a 1999 open-source engine: shadow maps, per-pixel lighting, reflections, bloom.

C++OpenGLGLSLx86 → C++ porting
private code
Stack

Tools I use daily.

Agents & LLMs
LILlamaIndex
AnAnthropic
OAOpenAI
CCClaude Code
Retrieval
QdQdrant
CoCohere rerank
EmEmbeddings
ChChunking
Backend & Cloud
FAPython / FastAPI
PGPostgreSQL
CRCelery / Redis
AWAWS (Cognito, SES, CDK)
Evals
LJLLM-as-judge
BSBootstrap CIs
Pypytest
Contact

Hiring for an AI engineer?
Let's talk.